
Qwen 4 is here, at least the top of it. Alibaba made Qwen4-Max generally available on November 16, 2026, five days after a limited preview, and the rest of the Qwen 4 family is still unreleased.
Pages written before launch day describe a preview with no price or benchmarks. Both are now public, and independent testers have already scored the model.
What Is Qwen 4?
Qwen 4 is Alibaba's fourth-generation family of Qwen models (Tongyi Qianwen in Chinese), and Qwen4-Max (also written Qwen 4 Max) is the first and so far only one you can use. Alibaba describes it as "built on the new Qwen4 architecture, with a 2.4-trillion-parameter backbone, native vision capabilities, and a one-million-token context window" in its official Qwen4-Max release post.
It is a sparse mixture-of-experts model: 71 billion parameters are active per token, plus a separate store of 328 billion N-gram embedding parameters. It reads text, images and video and answers in text.
| Spec | Qwen4-Max |
|---|---|
| API model ID | qwen4-max |
| Parameters | 2.4T backbone, 71B active per token, plus 328B N-gram embedding |
| Context window | 1,000,000 tokens |
| Max output | 262,144 tokens with thinking, 131,072 without |
| Input / output | Text, image, video in; text out |
| API formats | OpenAI Chat Completions and Responses, Anthropic Messages, DashScope |
| Tools | Function calling, web search, structured output (JSON Object and JSON Schema) |
| Rate limit | 5,000,000 tokens per minute at the entry tier |
| Open weights | None |
The limits come from Alibaba's official qwen4-max model documentation, which calls it "the next-generation flagship multimodal model in the Qwen family." Our guide to what Qwen is covers the earlier Qwen models and the open releases.
Qwen 4 Release Date: From Apsara to General Release
Qwen4-Max, Alibaba's new flagship, became generally available on November 16, 2026, Beijing time, which was still November 15 in the US. Alibaba's post is dated the 16th, while Vals AI lists the 15th.
Qwen 4 reached the public in stages. In late August, Alibaba released open weights for Qwen3.8-Flash-Next, a smaller model it described as built on the next-generation Qwen4 architecture.
At its Apsara conference on September 22, Alibaba's conference announcement said Qwen 4 "is currently in training" and that the later Qwen 4.5 and Qwen 5 series are projected to scale up to 5 to 10 trillion parameters. NYU Shanghai's write-up of the keynote noted a widely shared post on X that listed Max, Plus, Flash and 27B.
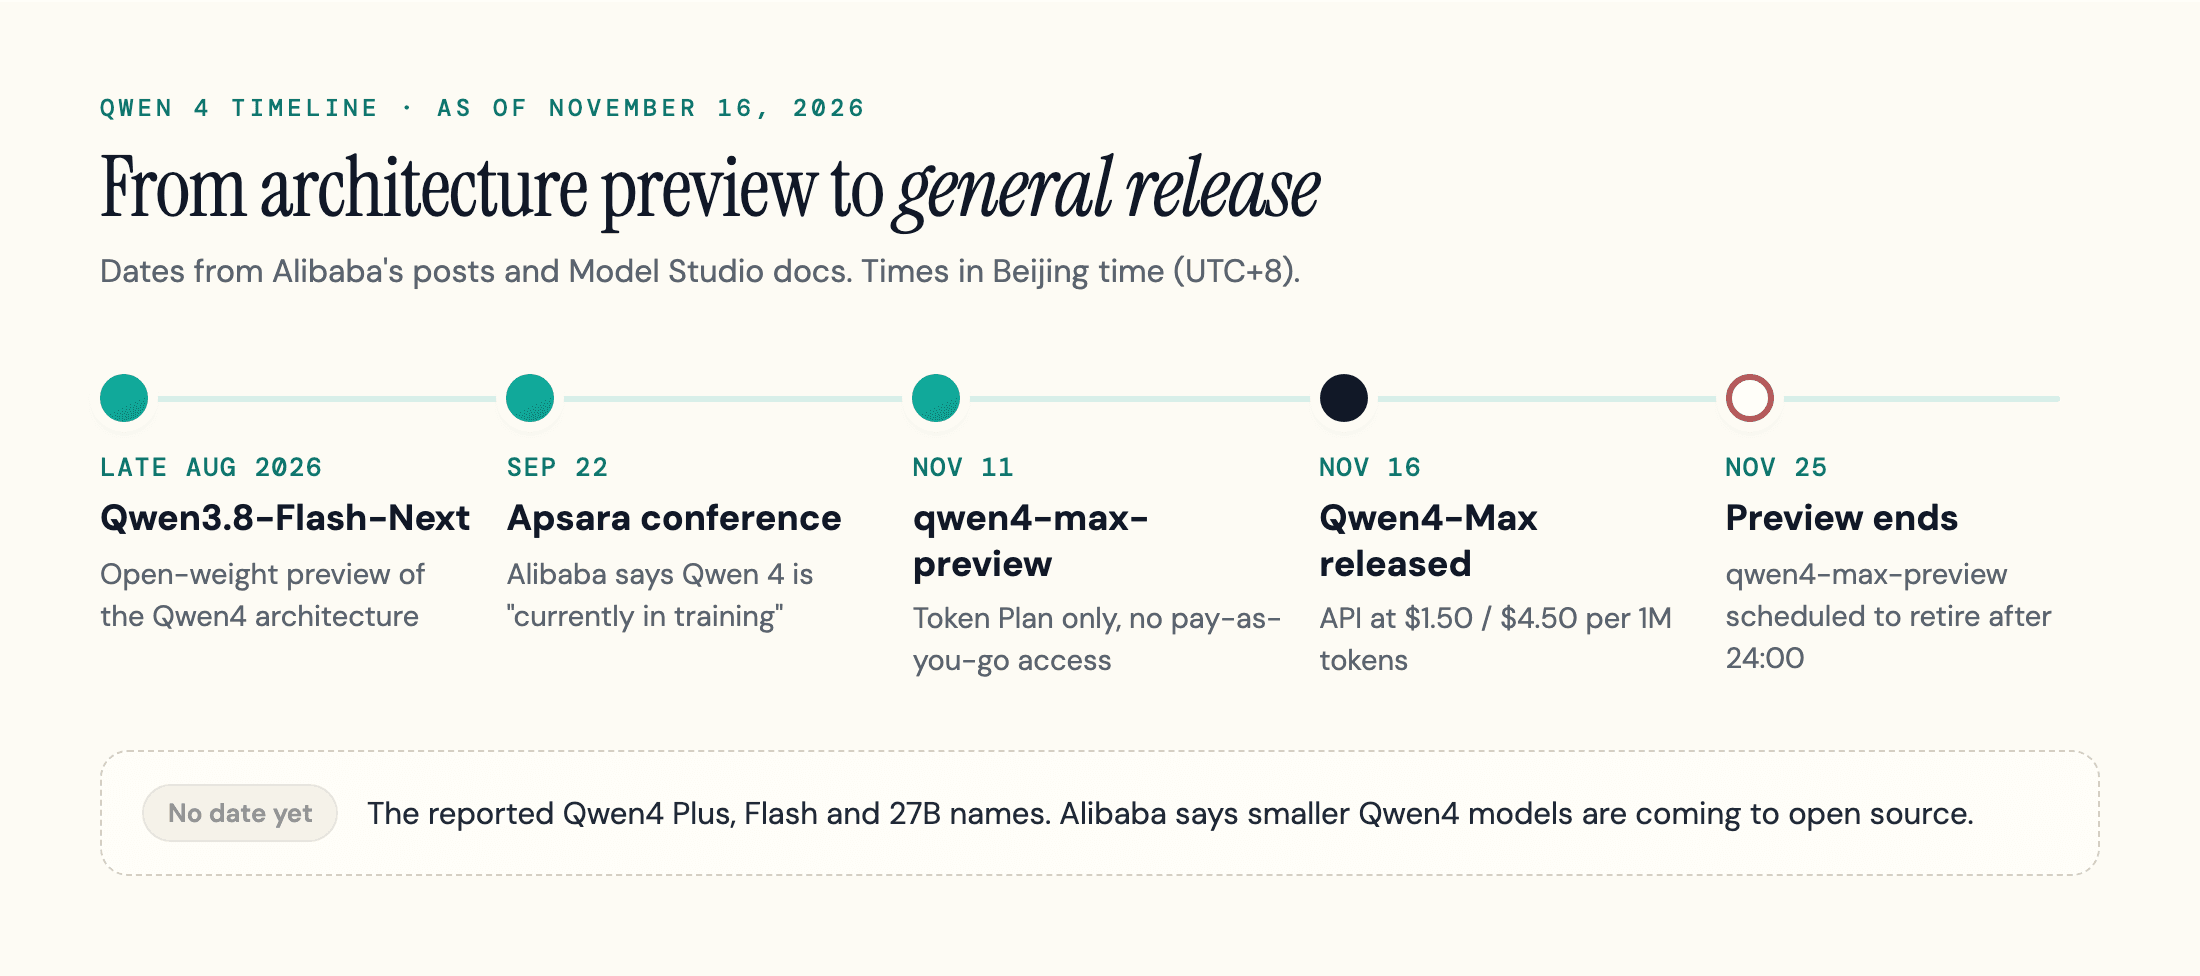
A preview came first. The qwen4-max-preview documentation sets its window from 10:00 on November 11 to 24:00 on November 25 (UTC+8), through Token Plan only, and says the preview model "will be retired after the preview ends."
Alibaba has not confirmed Plus, Flash or 27B by name. Its Qwen4-Max press release says only that open-weight, smaller-scale Qwen4 models "will soon be released."
Qwen4-Max Benchmarks: Alibaba's Chart vs Independent Tests
On independent tests, Qwen4-Max is the top-scoring Chinese model on the Vals Index, but Artificial Analysis ranks it 38th of 81, below Kimi K3.1 Pro and the leading US models.
Alibaba's chart compares Qwen4-Max with Qwen3.8-Max-0902, Claude Opus 5.5, GPT-6.1 Sol, GPT-6 Astra and Kimi K3.1 (Kimi-K3.1-Pro elsewhere in the same post) across 16 tests. Its footnotes say several scores, including the legal and Agents' Last Exam results, are taken from third-party boards.
Qwen4-Max scores highest of the six on 4 of the 16: agentic coding on DeepSWE (75.7, a 0.2-point edge over Kimi's 75.5), Agents' Last Exam (46.7 against 43.4), legal agent work on HLAB-Vals (21.3 against 15.4 for Qwen3.8-Max) and BioMysteryBench (85.0 against 84.4).
It trails the best rival on the other 12. Among the widest gaps are Terminal-Bench 4.0 (48.5 against Kimi's 67.2), ProgramBench (31.5 against Opus's 65.0) and both vision tests: Chartography (54.2 against GPT-6 Astra's 71.1) and Video-Index (68.1 against 76.7).
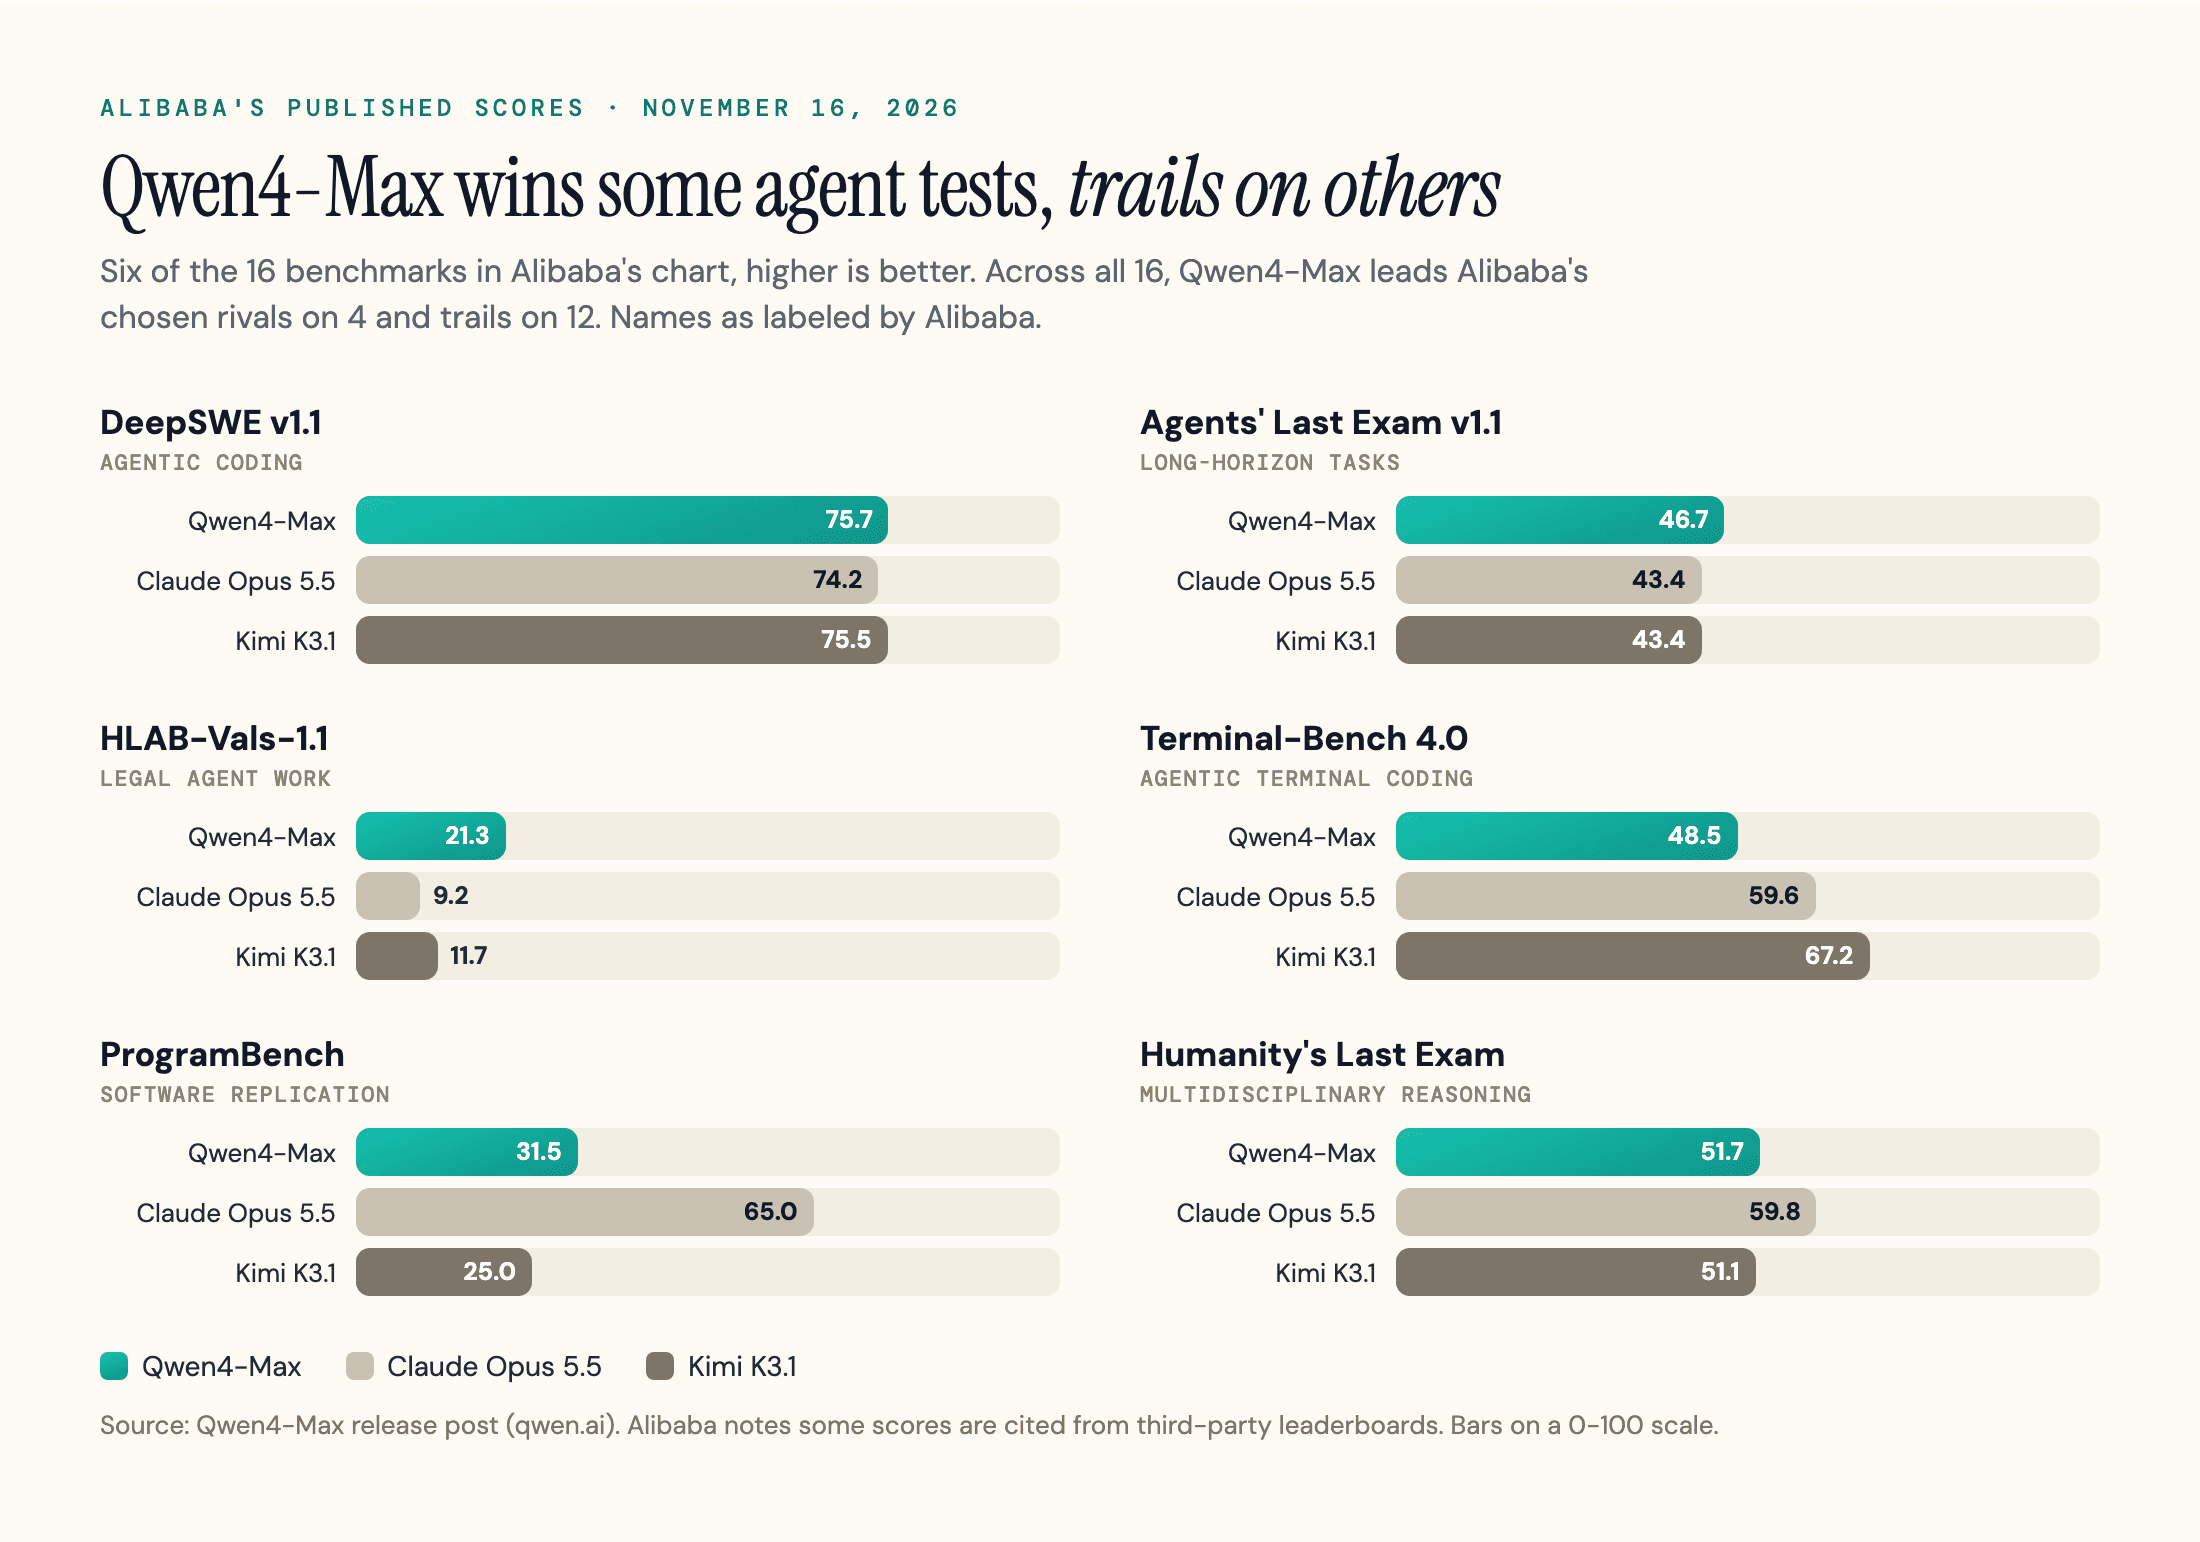
The legal lead holds only inside Alibaba's chosen set. On Vals' own HLAB board, Qwen4-Max ranks 7th, behind Gemini 4 Argon (27.08%) and five other models Alibaba did not chart.
Independent results arrived within a day. The one Alibaba-run score we could cross-check, Terminal-Bench 4.0, matches Alibaba's:
| Measure | Qwen4-Max | For comparison | Measured by |
|---|---|---|---|
| Vals Index | 63.20% (#11 of 38) | Kimi K3.1 Pro 62.52%; Qwen 3.8 Max 0902 59.05% | Vals AI |
| Terminal-Bench 4.0 | 48.48% (#15 of 65) | Alibaba reported 48.5 | Vals AI |
| Intelligence Index | 43 (#38 of 81) | Claude Fable 5.2 65, Gemini 4 Carbon 60, Opus 5.5 59, GPT-6.1 Sol 55, Kimi K3.1 Pro 46 | Artificial Analysis |
Vals AI's model page calls it the highest-scoring Chinese model on its index, 0.7 points ahead of Kimi K3.1 Pro. Artificial Analysis rates it "above average" at 43, up from 34 for the 0902 snapshot of Qwen3.8-Max. Alibaba's chart leaves out the models at the top of that index, Claude Fable 5.2 and Gemini 4 Carbon.
Work360, where Qwen4-Max scored 52.69 against 47.74 for Qwen3.8-Max, is a benchmark Alibaba built itself, and we found no outside run of it yet. Our comparison of Chinese AI models covers DeepSeek, Kimi and GLM.
Qwen4-Max Pricing: Cheaper per Token, Not Always per Task
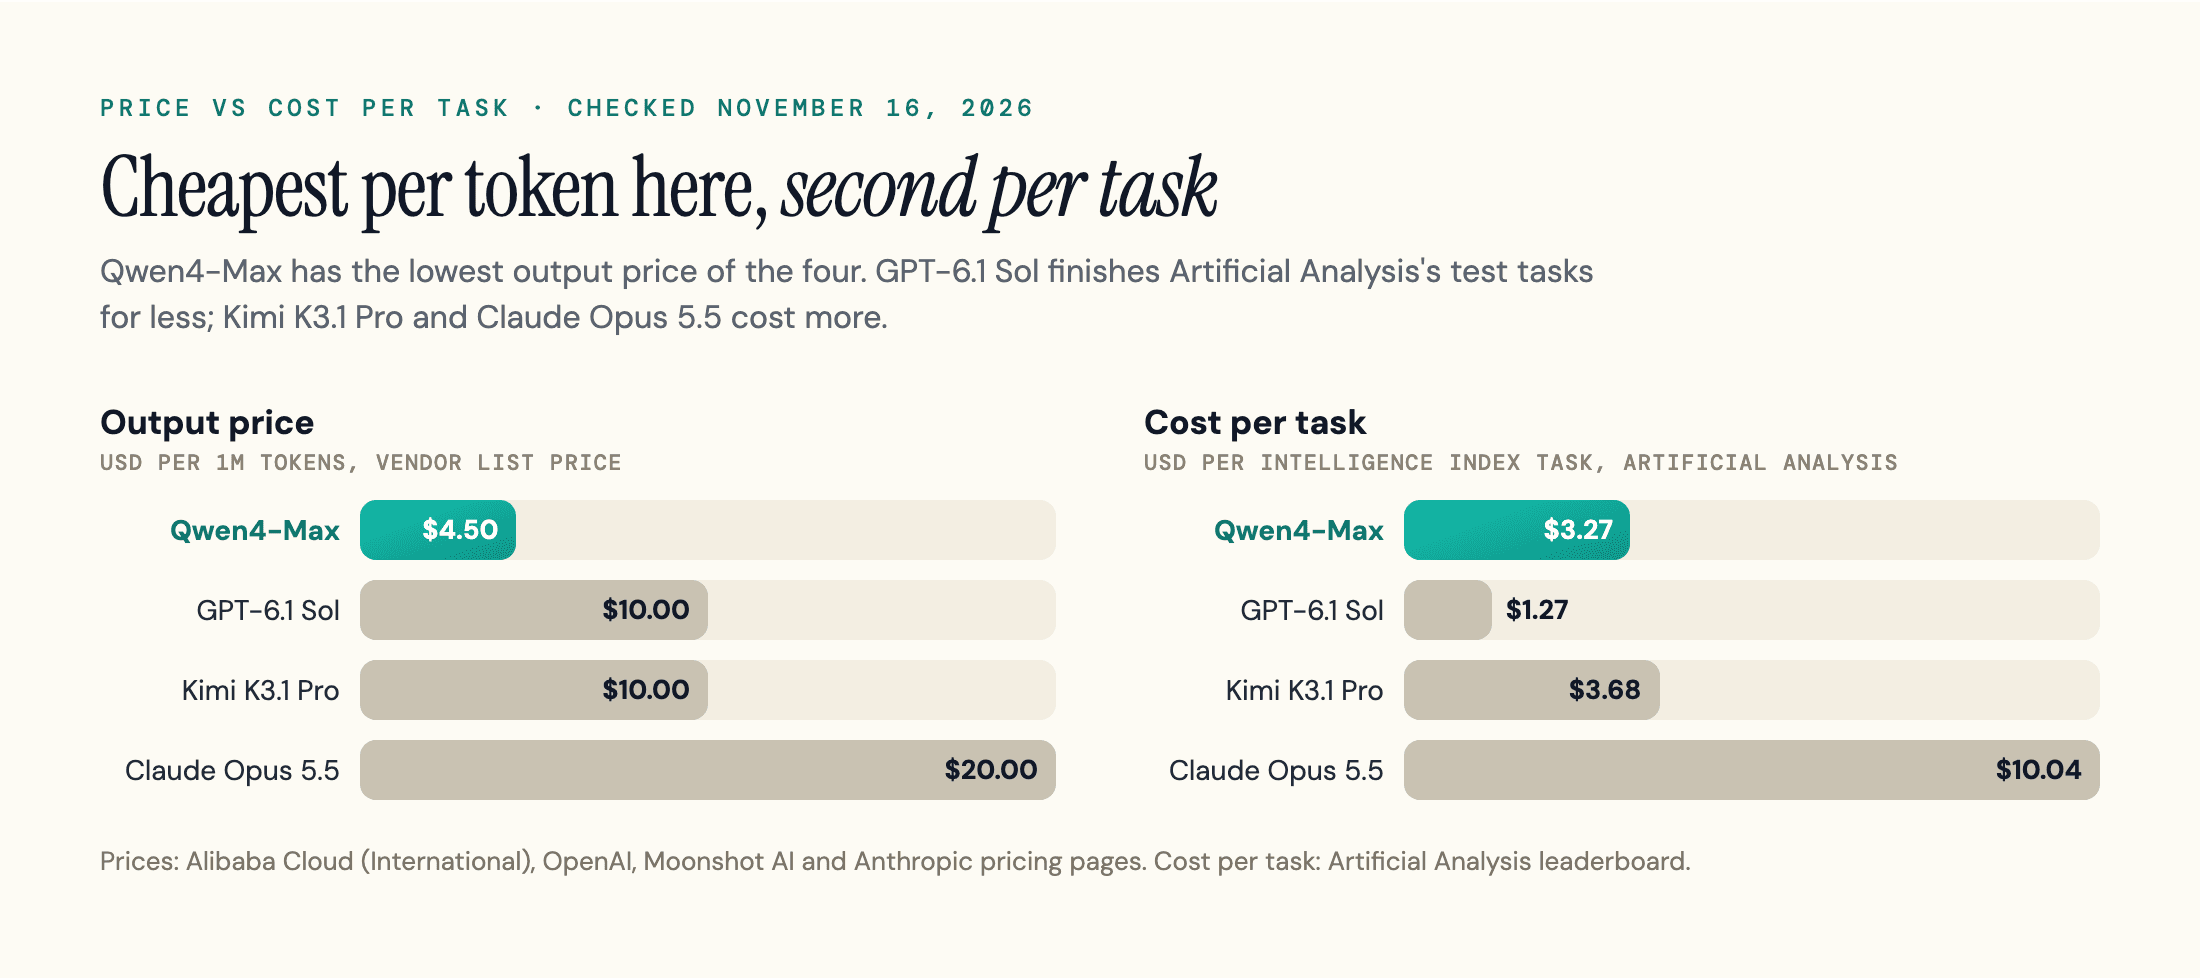
Qwen4-Max costs $1.50 per million input tokens and $4.50 per million output tokens on Alibaba Cloud's International endpoint, 25% less than Qwen3.8-Max's $2 and $6.
According to Alibaba Cloud's official model pricing page, cached input reads cost $0.075 and cache writes $1.875 (5-minute) or $3 (1-hour). Model Studio accounts in Singapore get 1 million free tokens valid for 90 days. In the US (Virginia) region the model is listed only under a Global deployment scope, at $1.413 and $4.24.
| Model | Input / output per 1M tokens | Cost per Intelligence Index task |
|---|---|---|
| Qwen4-Max | $1.50 / $4.50 | $3.27 |
| GPT-6.1 Sol | $2 / $10 | $1.27 |
| Kimi K3.1 Pro | $2 / $10 | $3.68 |
| Claude Opus 5.5 | $4 / $20 | $10.04 |
GPT-6.1 Sol charges 2x for input and 1.5x for output on prompts above 272K input tokens; Qwen4-Max keeps one rate up to 1M. The last column comes from Artificial Analysis, which lists GPT-6.1 Sol and Opus 5.5 at their max effort setting and gives no effort label for Qwen4-Max or Kimi K3.1 Pro.
Qwen4-Max is cheaper per token than GPT-6.1 Sol but costs more per task. It uses far more tokens to get there: Artificial Analysis counted 9.9 billion input and 127 million output tokens for its index run, against 1.92 billion and 63.7 million for GPT-6.1 Sol.
It is still cheaper per task than Kimi K3.1 Pro and Claude Opus 5.5, and about a third of the $10.02 that Qwen3.8-Max (0902) cost, in line with the 62% cut ($4.43 to $1.67) Alibaba reports on Work360.
Models outside Alibaba's chart can be cheaper still: Artificial Analysis lists GPT-6.1 Terra at 51 on its index for $0.96 per task. Our explainer on AI token costs shows how to estimate the bill for your workload.
How to Use Qwen4-Max Today
Alibaba's release post says Qwen4-Max "is now available on QwenCloud. You can start building with either the Token Plan or the API."
- Pay-as-you-go API. Create a Model Studio key and set the model to
qwen4-max. The endpoint accepts OpenAI and Anthropic request formats, so most clients need only a new base URL, key and model string. - Token Plan. Alibaba's credit-based subscription, and the only way into the preview. Alibaba has not published how many tokens a credit buys.
- Alibaba's apps. The post also lists QwenWork, Qoder and QwenStudio. Guests in Alibaba's chat app at chat.qwen.ai could not pick Qwen4-Max on launch day (see the FAQ).
- OpenRouter. OpenRouter lists it as
qwen/qwen4-max, served by Alibaba at $1.50 and $4.50 and, on November 16, also by Novita at $1.413 and $4.24.
Thinking is on by default. The documented reasoning_effort values are low, high and xhigh, with high as the default. Output is billed as chain of thought plus answer, so the effort setting is a direct cost lever. preserve_thinking is also on by default, carrying earlier reasoning across turns.
Alibaba's preview notes say max_tokens now covers thinking and the answer combined, so leave room for both. Keep the model string in configuration, since qwen4-max-preview is retired after November 25. And because cost per task depends on how many tokens a model reads and writes across turns, run a few dozen of your own prompts before moving production traffic.
What Changed from Qwen3.8-Max
Qwen4-Max keeps the 2.4-trillion-parameter scale of Qwen3.8-Max but activates fewer parameters per token: 71 billion instead of 95 billion. The release post attributes the gains to the new Qwen4 architecture, and our Qwen3.8-Max guide covers the model it replaces.
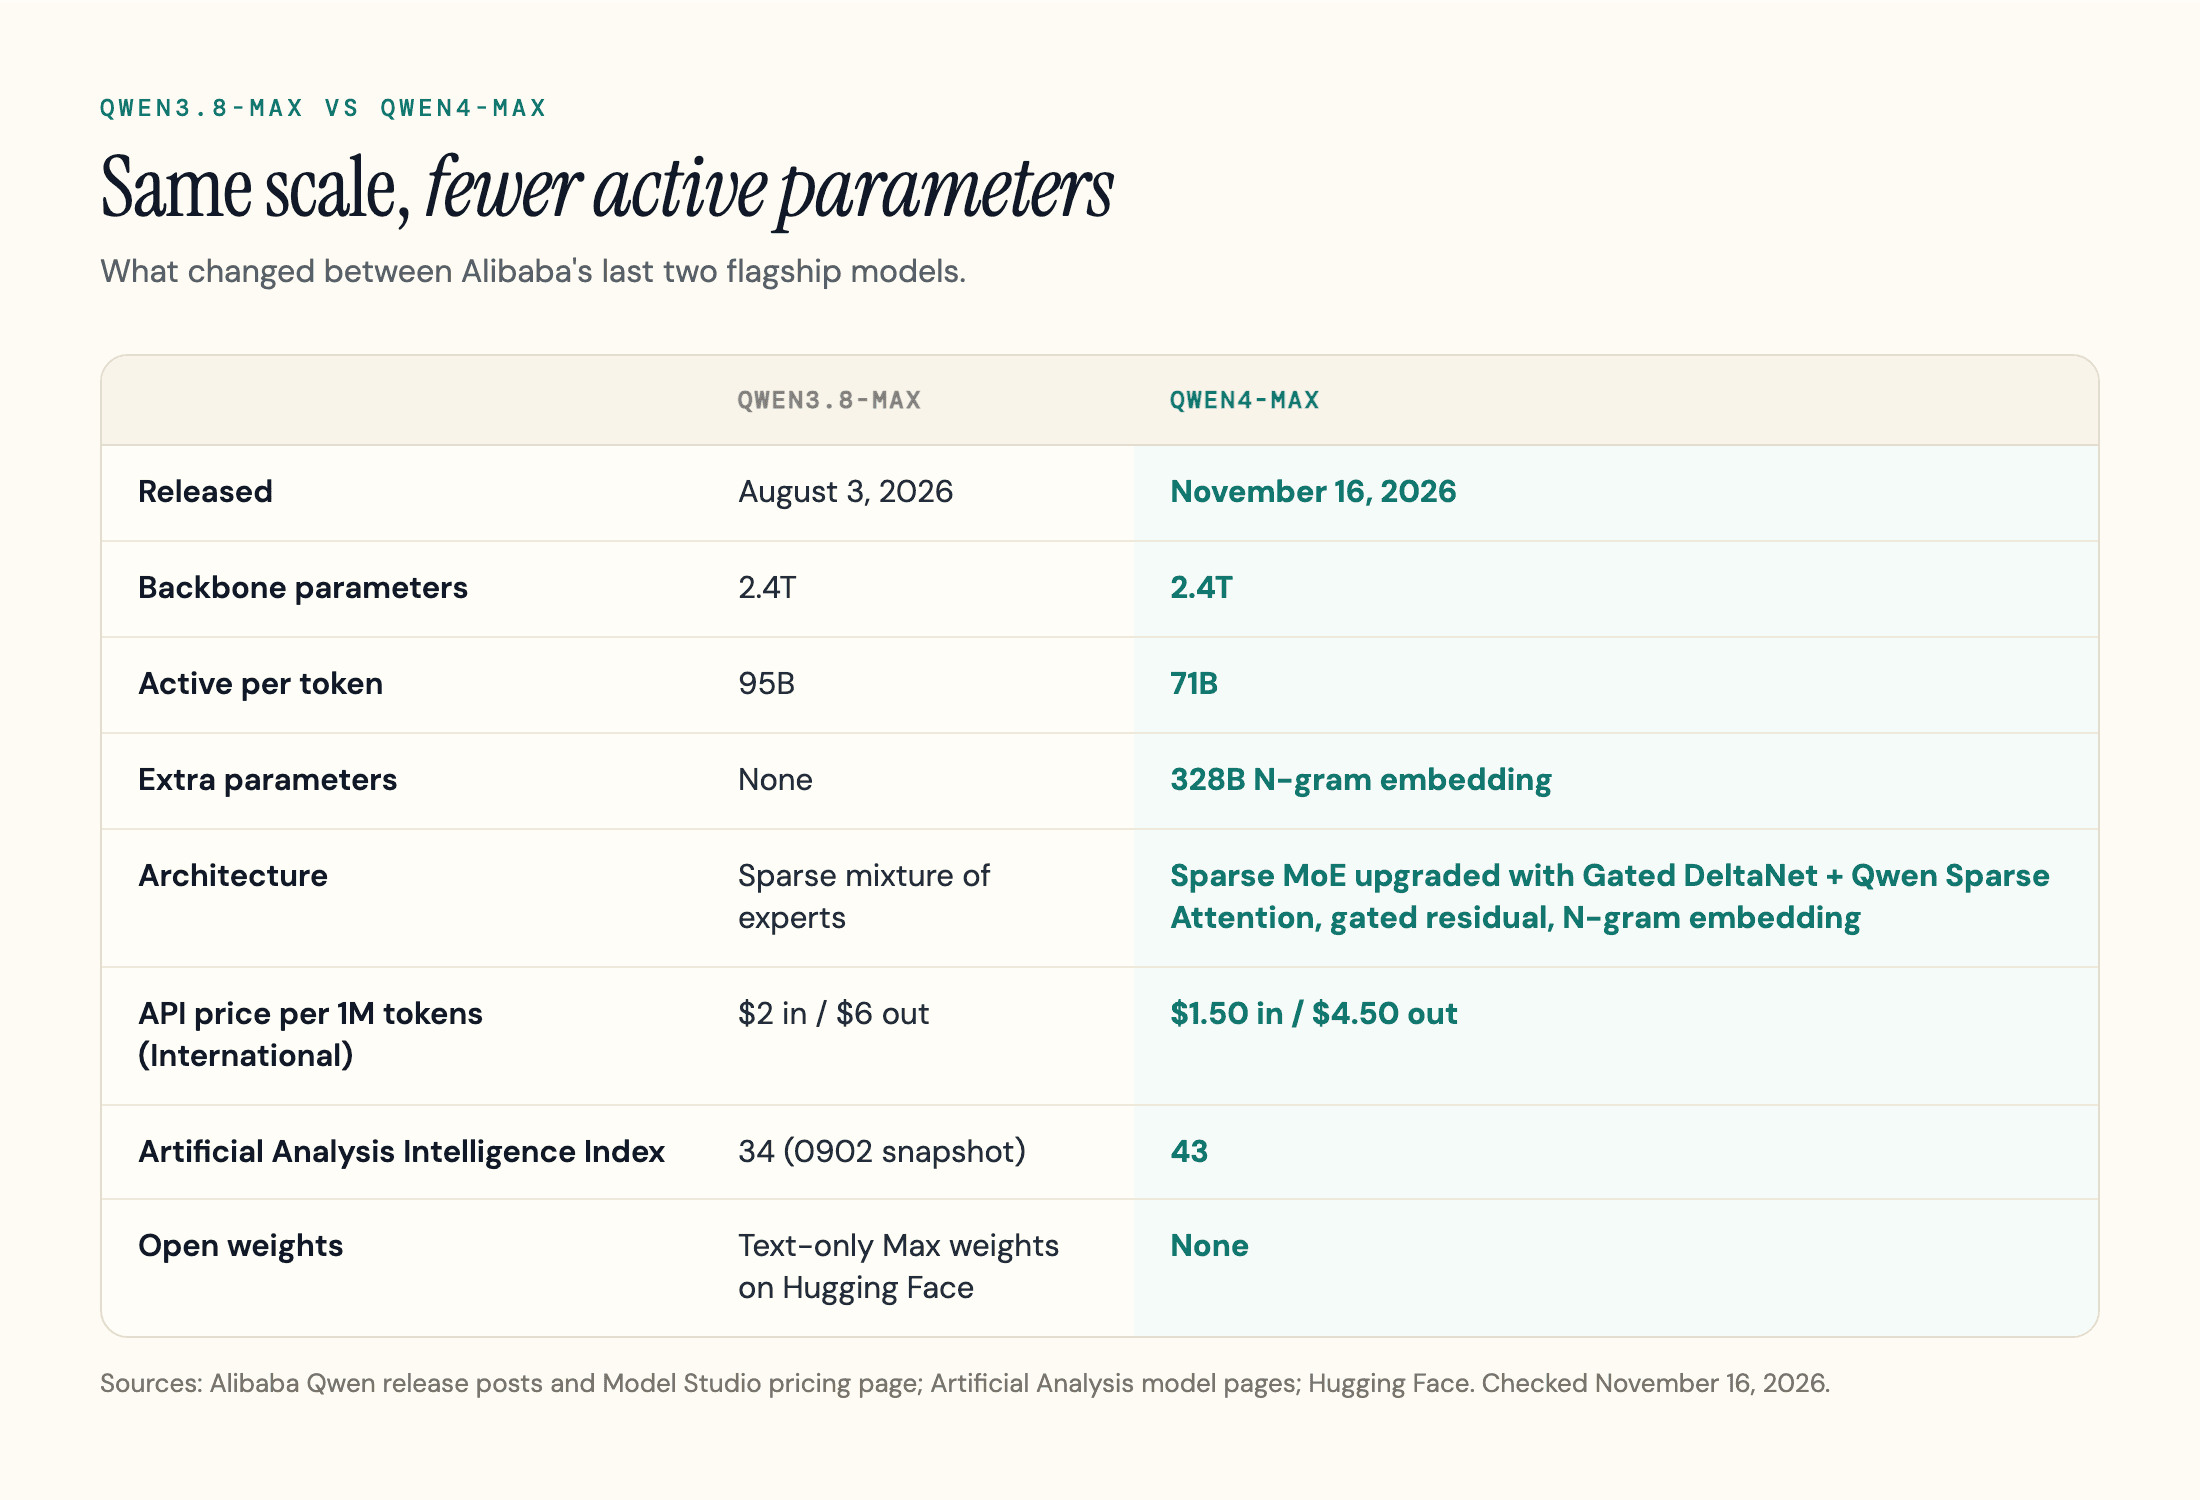
Gated DeltaNet layers paired with Qwen Sparse Attention make long contexts cheaper to process. Gated residual connections keep training stable. A 328-billion-parameter N-gram embedding looks up representations of local token patterns, which expands capacity with little extra computation.
On Alibaba's in-house tests, the base model reaches about 5 to 13% lower bits per byte, a prediction-error measure where lower is better.
Qwen4-Max also writes less than its predecessor, though it stays verbose next to rivals. Alibaba reports token use down about 48% on Terminal-Bench 4.0 at the highest effort, and Artificial Analysis counted 127 million output tokens against 150 million for Qwen3.8-Max (0902). On Last Secure Code Bench, Alibaba says the share of code that is both working and secure rose from 22.0% to 31.8%.
Alibaba also says it removed training data for offensive cyber tasks and that the model answers risky chemical, biological and nuclear requests safely "without exhibiting over-refusal." We found no independent test of those guardrails yet.
Is Qwen 4 Open Source?
No. Qwen4-Max has no public weights, and no other Qwen 4 model has shipped yet. A search of Alibaba's Qwen organization on Hugging Face on November 16, 2026 returned no Qwen4 models, and the release post says only that "smaller models in the family are coming to open source." Repositories elsewhere on Hugging Face titled "Qwen4-27B" come from third parties.
To run something from this generation on your own hardware today, the option is Qwen3.8-Flash-Next, Alibaba's open preview of the Qwen4 architecture: 125 billion parameters with 6 billion active, plus a 51-billion-parameter N-gram embedding, under the Qwen Community License 1.0. The 27B has no published specs, so there is nothing yet to size hardware against.
Alibaba has opened a Max-tier model before: Qwen3.8-Max's text-only weights reached Hugging Face days after its API launch, under a custom license. The Qwen4-Max post makes no such promise. Our guide to open weights vs open source explains why those licenses matter.
What Early Users Report
Most hands-on reports so far come from the preview, before general release. One tester in an r/Qwen_AI comparison thread summed it up as "pretty good, not frontier (i.e. Astra) but a step behind (i.e. Sol), a bit slow."
Speed comes up often. In the r/Qwen_AI launch thread, one preview user said "the token output is extremely slow (between 21 to 42/s)." After release, OpenRouter measured about 43 tokens per second on Alibaba's endpoint on November 16.
In an r/singularity thread, some point to "a 9 point jump over 3.8 max from 3 months ago at least," while others question the value next to cheaper flash-tier models.
Why a New Qwen Matters for Your AI Visibility
The engines we tested without web access did not know Qwen4-Max existed on launch day, and the same lag applies to your own brand news. On November 16, 2026, geotoolbox asked the major AI engines eight questions about Qwen 4. Gemini 3.8 Flash with web search off replied: "As of May 2024, there is no model named 'Qwen 4' or 'Qwen4-Max.'" Claude with no tools also said it had no reliable knowledge of Qwen 4.
Every engine with web access (ChatGPT, Gemini, Perplexity, Google AI Mode and Claude with search) returned the $1.50 and $4.50 prices within hours. For anything new, what an engine says depended on the pages it could fetch and cite, which is the core of AI visibility.
The same gap applies when you launch a product or change a price. geotoolbox's AI visibility tracker runs your prompts through the major AI engines on a schedule, so you can see when the old answer is replaced.
Frequently Asked Questions
Is Qwen 4 free?
Not for guests. On launch day, the logged-out model picker at chat.qwen.ai offered Qwen3.7-Plus and Qwen3.8-Max but not Qwen4-Max, and we could not check logged-in accounts. On the API side, Model Studio gives Singapore accounts a 1-million-token free quota for 90 days.
Does Qwen train on your data?
Not through Alibaba Cloud Model Studio, according to its privacy notice: "Alibaba Cloud strictly protects your data privacy and will never use your data for model training." Its data retention policy keeps prompts and responses from inference calls for up to 30 days by default, longer where law or security requires; stored conversations and files follow separate rules. Alibaba's consumer apps run under their own terms.
Is Qwen 4 good at coding?
It depends on the task. Vals ranks Qwen4-Max 15th of 129 on Vibe Code Bench (86.66%) and 15th of 65 on Terminal-Bench 4.0 (48.48%). In Alibaba's own chart it leads DeepSWE but trails Kimi K3.1 and Claude Opus 5.5 on terminal work.
Sources
- Qwen4-Max: Your New Teammate Has Arrived (release post, specs, benchmark chart) - Qwen / Alibaba, November 16, 2026 -
qwen.ai/blog?id=qwen4-max - Alibaba Unveils Qwen4-Max (press release) - Alibaba Cloud, November 16, 2026 -
alibabacloud.com/en/press-room/alibaba-unveils-qwen4-max - Model Studio model pricing (qwen4-max and qwen3.8-max rates by region) - Alibaba Cloud -
alibabacloud.com/help/en/model-studio/model-pricing - qwen4-max and qwen4-max-preview model documentation - Alibaba Cloud Model Studio -
help.aliyun.com/en/model-studio/qwen4-max - Model Studio privacy notice and data retention policy - Alibaba Cloud -
alibabacloud.com/help/en/model-studio/privacy-notice - Alibaba Unveils Roadmap on Full-Stack AI Strategy (Apsara 2026) - Alibaba Cloud, September 2026 -
alibabacloud.com/en/press-room/alibaba-unveils-roadmap-on-full-stack-ai-strategy - Alibaba at Apsara 2026: Qwen 4 in Training, 10T Models Next - NYU Shanghai RITS, September 2026 -
rits.shanghai.nyu.edu/ai/alibaba-at-apsara-2026-qwen-4-in-training-10t-models-next - Qwen 4 Max model page and HLAB-Vals board - Vals AI -
vals.ai/models/alibaba_qwen4-max - Qwen4 Max: Intelligence, Performance and Price Analysis - Artificial Analysis -
artificialanalysis.ai/models/qwen4-max - Qwen: Qwen4 Max providers and throughput - OpenRouter -
openrouter.ai/qwen/qwen4-max - Qwen organization model list and Qwen3.8-Flash-Next model card - Hugging Face -
huggingface.co/Qwen - GPT-6.1 Sol, Kimi K3.1 Pro and Claude Opus 5.5 pricing pages - OpenAI, Moonshot AI, Anthropic, checked November 16, 2026 -
developers.openai.com/api/docs/models/gpt-6.1-sol,platform.kimi.ai/docs/pricing/chat,platform.claude.com/docs/en/about-claude/pricing - Qwen4-Max launch and comparison threads (user reports) - r/Qwen_AI and r/singularity, November 2026 -
reddit.com/r/Qwen_AI